Our commitment to global sustainability
10. March 2022
Vibe coding has limits – your architecture shouldn’t
24. October 2026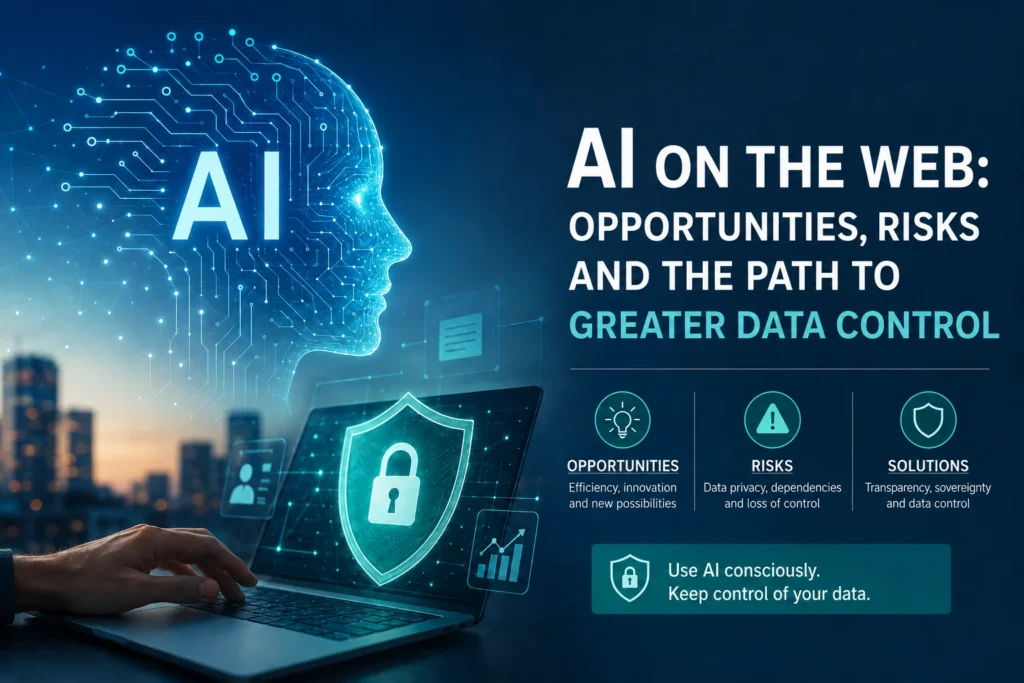
AI tools on the web offer great opportunities for working more efficiently, but they also bring new data protection risks. Anyone who enters sensitive or personal data into external AI services quickly loses control over where this information is processed, stored or reused. Prompts, uploaded documents, chat histories and metadata are particularly critical.
From a GDPR perspective, it is therefore crucial which data is used, for what purpose it is processed and whether there are clear rules for using AI. Organizations should define which information may be entered into external AI systems and which may not. AI is not inherently problematic, but it requires a deliberate and controlled approach to data.
AI on the web:
Opportunities, risks and the path to greater data control
Artificial intelligence has long since arrived in everyday work. Summarizing texts, drafting emails, checking contracts, designing concepts or analyzing documents: what used to take a lot of time, AI systems now often do in a few seconds. For companies, associations, educational institutions and public administrations, this is a great opportunity.
At the same time, a new challenge arises: anyone who uses AI often processes data. And this data is often sensitive, confidential or even personal. This is exactly where AI and the GDPR meet.
Why AI is not just a productivity tool
Many AI services are used directly in the browser. You open a website, type in a question, perhaps upload a document and get an answer. It seems simple and harmless. Technically, however, much more is happening: the text you enter, the file, the chat history and sometimes metadata are transferred to an external service.
This is particularly relevant when personal data is involved. This includes not only names, addresses or email addresses. Internal meeting notes, job applications, customer data, project information or health data can also fall under the GDPR.
The key question is therefore not: “Is AI allowed?”
The better question is: “Which data is processed where, for what purpose and under what conditions?”
Typical risks of AI services on the web
A major risk is that users enter data into external AI systems without knowing exactly what happens to it afterwards. Are the prompts stored? Are they used to improve the service? Can the provider’s staff access them? Where are the servers located? Is there a data processing agreement? Is data transferred to third countries?
These questions are not theoretical. In practice, content quickly ends up in AI tools where it does not belong: internal strategy papers, customer letters, draft contracts, code, personnel information or support cases.
Another risk concerns traceability. Many AI systems deliver convincingly worded answers without always making clear which sources they are based on. This can lead to wrong decisions. An AI can invent content, misrepresent relationships or overlook important limitations. This phenomenon is often referred to as hallucination.
Confidentiality is also an issue. Anyone who uploads a sensitive contract or internal minutes to a public AI tool gives up control over this information, at least in part. Even if the provider is reputable, the organization must check whether the use meets its data protection and security requirements.
GDPR: not every use of AI is problematic
Importantly, the GDPR does not prohibit AI. It does, however, require personal data to be processed lawfully, transparently, for specified purposes and to an appropriate extent. Among other things, this means: it must be clear which data is processed, why this happens, who has access and when the data is deleted.
For organizations, this means that using AI needs rules. Employees should know which information they may enter into external AI systems and which they may not. Without a clear policy, a shadow IT problem quickly arises: everyone uses their own tools, but nobody has an overview.
A simple classification can help:
Public information can often be processed without concern. Internal information should only be used with approved tools. Personal or confidential data requires special review. Highly sensitive data should generally not be entered into external web-based AI systems unless there is a clear legal and technical basis.
The real problem: loss of control
The core of many data protection risks lies not in AI itself, but in the loss of control. As soon as data leaves a controlled environment, organizations have to trust that the external service works correctly, securely and in compliance with the law.
This can be possible, but it requires review: contracts, technical measures, storage locations, deletion concepts, access protection and transparency. Smaller organizations in particular often lack the resources for this.
That is why interest in alternatives is growing: local AI systems, private AI infrastructures and solutions in which data remains in your own environment.
Conclusion: AI needs data awareness
AI can bring enormous benefits. But it changes the way we handle information. What used to stay in an internal document is now quickly copied into a web form. It is precisely this moment that determines whether AI is used responsibly.
The first step towards privacy-friendly AI is therefore not a technical one, but an organizational one: companies need to understand what data they have, how sensitive it is and which AI tools are suitable for it.
The next article looks at how local AI and self-hosting can help you gain more control over data, processes and infrastructure.